AI-Assisted Testing Adds a Validation Layer, It Doesn't Remove One
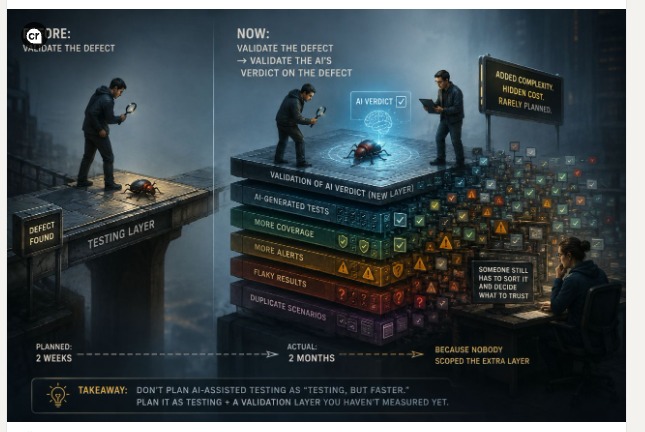
AI testing doesn’t remove a layer of work. It adds one.
- Before: validate the defect.
- Now: validate the defect → validate the AI’s verdict on the defect.
Two weeks became two months
I scoped an AI-assisted testing rollout at two weeks. It took two months.
Not because the tools failed. They did what they were supposed to do. It took two months because nobody — me included — accounted for the validation overhead. The estimate covered getting the tools in and generating tests. It didn’t cover the work that shows up after the tests exist.
That’s one rollout, one team, my experience. Your numbers will differ. But the shape of the problem hasn’t been unique when I’ve described it to others.
Where the extra layer comes from
More AI-generated tests means more coverage — and more of everything that comes with it:
- more alerts,
- more flaky results,
- more duplicate scenarios that look different but check the same thing,
- more “is this a real failure or did the AI misread the requirement?”
Someone still has to sort through all of it and decide what to trust. That sorting is the hidden cost.
It doesn’t show up in planning because there’s no reference point yet for how long “validating the validation” takes. We have decades of intuition for how long it takes to validate a defect. We have close to none for how long it takes to validate an AI’s verdict on a defect — and every team is building that intuition from scratch, usually mid-rollout.
What I’d do differently
- Name the layer in the plan. Treat AI-assisted testing as testing plus an unmeasured validation layer — not as “testing, but faster.” If the estimate has no line for triage, it’s missing a line.
- Budget for someone to own the triage. Not “the team will handle it.” A person, with time allocated, whose job is deciding what to trust.
- Measure the layer as you go. Since there’s no reference point, build one: how long triage takes per batch of generated tests, how much of it is duplicates, how much is real signal. That number is what makes the next estimate honest.
Still faster than testing without AI, in my case — just significantly slower than expected going in. The gap between those two is exactly the layer nobody scoped.
Supporting evidence
Two sources back the pattern beyond my own rollout. Neither is a controlled measurement of the overhead itself — that number doesn’t exist yet, which is the point.
- AI-written tests can inherit the bugs they’re meant to catch. A study on the common “code first, then generate tests” workflow found LLM tests written after buggy code detect far fewer faults than tests written independently — 14% vs. 25% fault-detection effectiveness. Faults in the generated code get baked into the matching tests; code and tests stay consistent while both miss the defect. That’s the kind of thing a human has to catch, and it doesn’t catch itself. (arXiv preprint 2607.05139, submitted 2026-07-06, not yet peer-reviewed — abs)
- People overestimate how much faster AI makes them. A METR survey of 349 technical workers (Feb–Apr 2026, published 2026-05-11) found a self-reported median speed-up of roughly 3x from AI — and METR’s own analysis flags that as likely overstated, citing a prior finding that people overestimate AI’s time savings by about 40 percentage points. Self-report data, not a controlled measurement, and the best I found within the recency window for this angle. (METR, May 2026)
Where this goes next
- Processes / estimation: what “name the layer” looks like as an actual line item in the estimate — and how you size a triage line when there’s no baseline to size it from.
- Processes / ownership: triage as a real role with decision authority, not a default fallback to whoever notices the alert first — and what “handled” costs when nobody owns it.
- Testing / measurement: a minimal 3-number triage log — time per batch, share that’s duplicates, share that’s real signal — to build the reference point that’s missing today.
- Testing / coverage: duplicate AI-generated scenarios that inflate the coverage number without adding any real safety net — and how to tell the two apart.