The Afternoon I Lost to a Prompt: Technique Without Measurement Runs Blind
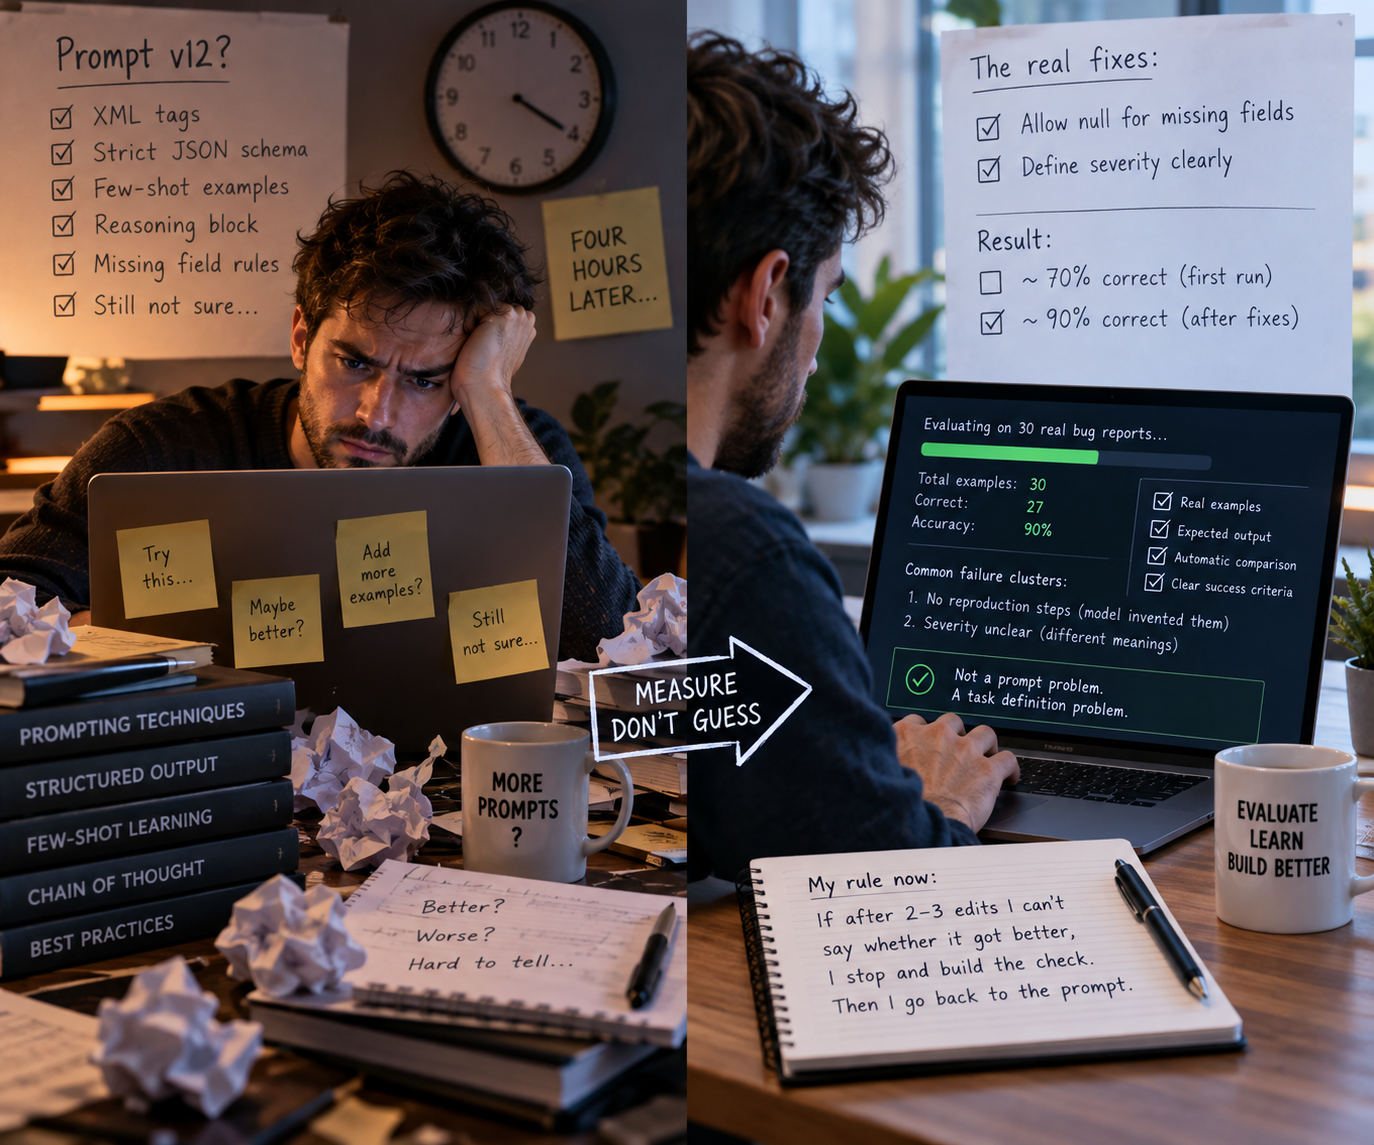
I know how to prompt, and I still lost half a day — because I was improving a prompt with no way to measure it.
That’s the whole post. The rest is how it happened, what a 40-minute script told me that four hours of careful editing couldn’t, and the rule I work by now.
The task
Parse bug reports from the tracker and return JSON: component, severity,
reproduction_steps. The output feeds automated triage, so it has to be machine-usable, not
“mostly right.”
Routine extraction work. The kind of thing a model should do well, and the kind of thing I should be able to set up quickly.
Four hours, by the book
I’m not a naive experimenter here. I completed Claude Certified Developer - Foundations, and I applied what it teaches, step by step:
- XML tags separating instructions, context, and the input report.
- An explicit JSON schema and a strict output format.
- Few-shot examples — three to five pairs of report → expected JSON, chosen to cover different cases.
- A reasoning block before the JSON, so the model works through the report before committing to fields.
- An explicit rule for what to do when a field isn’t found.
Every one of those steps was justified. Every one of them visibly helped on an individual report. And after roughly four hours I could not answer the only question that mattered: is the prompt better overall than it was this morning?
I was checking against the four or five reports I had open. Fix one, re-run, see it pass, move on. Whether the fix broke a report I’d checked an hour earlier — no idea. Whether the “improvement” was real or just the one case in front of me — no idea. Each edit was locally reasonable and globally unmeasured.
That’s not a prompting failure. That’s a measurement failure wearing a prompting costume.
Forty minutes that should have come first
The turning point was embarrassingly small. I stopped editing the prompt and wrote a script:
- About 30 real reports from the tracker.
- The expected fields for each, written down by hand.
- An automatic comparison: run the prompt, diff the JSON against the expected values, print the score.
Roughly 40 minutes of work. First run: about 70% correct.
Then the part that four hours of prompt editing had hidden: the failures weren’t spread around. They clustered into two groups. And neither group was caused by the prompt.
What the errors actually were
Group 1 — about half the failures: reports with no reproduction steps. There was nothing to extract, so the model invented steps. A confident, well-formatted, plausible list of steps that nobody had written. My “rule for missing fields” hadn’t covered this because the reports I was testing on all had steps — the few-shot examples were chosen for variety in the content, not for absence of it.
Group 2 — severity meant different things to different people. Not to the model — to
the team. The reports themselves used “severity” inconsistently, because we had never
written down what it meant. The model’s “wrong” answers were, in a few cases, defensible
readings of an undefined word. A good prompt cannot fix a badly-defined task.
Two fixes followed, neither of them a prompting technique:
- Allow
nullforreproduction_steps, and say so in the schema. - Write down a severity definition — one paragraph, agreed with the team — and put it in the context.
Another roughly 20 minutes. Score: about 90%.
Four hours of correct technique: couldn’t tell if it was improving. One hour of measurement and task definition: 70% to 90%, with a number I could show someone.
Why “I know how to prompt” wasn’t enough
The uncomfortable part is that nothing I did in those four hours was wrong. Anthropic’s own prompt engineering guide (living document, undated; fetched 2026-10-14) opens by assuming you already have “a clear definition of the success criteria,” “some ways to empirically test against those criteria,” and only then a first draft prompt — “If not, spend time establishing that first.” It also says plainly: “Not every success criteria or failing eval is best solved by prompt engineering.”
I had read that. I had skipped it anyway, because the task looked too small to deserve a harness. That’s the trap: the task was small enough that building the check felt like overhead, and large enough that I couldn’t hold the results in my head.
There’s a structural reason the head doesn’t work as a harness. Liu & Chu (Understanding the Prompt Sensitivity, arXiv 2604.18389, ACL 2026, 2026-04-20; I’ve read the abstract, not the full paper) report that prompt templates typically influence the model’s output distribution more than the questions themselves, that meaning-preserving rewrites of a prompt are dispersed in their effect, and that this sensitivity is hard to reduce to zero. If reformatting a prompt moves the output more than the input does, then “it worked on these five” tells you almost nothing about the other twenty-five.
Corsi et al. (Prompt Sensitivity in LLM-Based Essay Scoring is Model-Specific, EDM 2026, June 2026) measured this across GPT-5.4, Claude Opus 4.6, and Gemini 3 Flash on a scoring task. What drove the variance differed per model. The best configuration differed per institution even for the same model. The gap between best and worst prompt configuration was 4-5 RMSE points, and the worst configurations scored below a naive baseline. Their conclusion: there is “no universal prompt recipe” — calibrate empirically, the way you’d tune hyperparameters.
Read that as the counter-view too, because it is one: sometimes calibrating the prompt does pay — but only when measured. The best-vs-worst gap in Corsi et al. is real money, and it was found by running configurations against a scored dataset, not by eyeballing a handful of outputs. “Calibrate empirically” has a precondition hiding in it: you can only calibrate against a measurement. Without the harness I wasn’t calibrating; I was guessing with good vocabulary.
That also cuts against the clean “it wasn’t the prompt” story, and fairly. Sometimes the
prompt fix is the right fix. My fix #1 — allow null — is arguably a prompt fix, not a
task fix; the line between the two is blurrier than my headline makes it sound. What the
harness gave me wasn’t proof that prompting was useless. It was the ability to tell which
gaps were the obvious ones.
The rule I work by now
Opinion, stated as such, and n=1:
Prompting skill does not replace measurement on real examples. Without measurement, even correct technique runs blind.
Concretely: if after two or three prompt edits I can’t say whether the result got better or worse, I stop editing and build the check — 20-30 real examples, expected outputs written by hand, automatic comparison. Then I go back to the prompt. Usually the first run of the check tells me the prompt isn’t where the problem is.
This connects to the cost-per-verified-result post: the iteration loop nobody invoices. Four hours of prompt editing is exactly that loop — paid for, unmeasured, and absent from any estimate. The harness is what turns it into a line item.
The honest gap
- This is one person’s afternoon. I searched for a survey measuring hours developers spend on prompt iteration and found none. I also found no study comparing “build a measurement harness first” against “iterate on the prompt first” for speed or outcome. The core claim here rests on my n=1 experience, and I’m presenting it as that.
- The nearest survey doesn’t cover this. BairesDev’s Q3 2026 Dev Barometer (705 developers, via Techzine, 2026-09-15) reports that 67% spend more time reviewing AI-written code and that time spent learning new tools rose from 4 to 9 hours a week — but it has no figure for prompt iteration. I’m citing it to show the gap, not to fill it.
- No practitioner source within 6 months matched this specificity. Practitioner write-ups on evals exist, but the ones concrete enough to quote are older than the recency bar I hold AI claims to, so they’re not cited here.
- All numbers in my story are approximate. “About 4 hours,” “about 30 reports,” “about 70% then about 90%” — I didn’t log them at the time. The direction is accurate; the decimals aren’t.
- The Liu & Chu citation is abstract-only and is about six months old, at the edge of what I’d cite for an AI claim. The sensitivity finding is consistent with Corsi et al., which I’ve read in full, but I haven’t checked Liu & Chu’s methodology.
- Corsi et al. measured essay scoring, not JSON extraction. The “model-specific sensitivity” result may transfer to structured extraction; I’m assuming it does, not showing it.
- “It wasn’t the prompt” is a simplification. Allowing
nulllives in the schema, which lives in the prompt. The honest version: the harness told me which two changes mattered, and neither was a technique from the course. - The Anthropic guide is undated. I fetched it 2026-10-14; it may have read differently when I took the course.
Where this goes next
- Testing / AI — the harness I built is not an eval, and that’s the next trap: 30 hand-labelled examples and a diff got me from 70% to 90%, but “expected fields written by hand” means the labels carry my own severity reading — the harness inherits the ambiguity it was meant to expose. The angle: take the same 30 reports, have two people label them independently, measure inter-annotator agreement per field, and show how much of the “90%” is the model agreeing with one person’s guess.
- AI / development — prompt or task? The line is blurrier than the story: “allow
null” lives in the schema, which lives in the prompt; the clean split between “prompting technique” and “task definition” that made this post’s headline work doesn’t survive contact with a real fix list. The angle: classify every edit from a real prompt-iteration session into technique / task definition / schema / data, and show which category actually moved the score — the hypothesis being that course-taught technique is the smallest bucket. - AI — does prompt sensitivity transfer from essays to JSON? the only recent sensitivity evidence cited above is essay scoring; I assumed it applies to structured extraction without showing it, and extraction may be far less sensitive — which would weaken the “your head can’t be the harness” argument. The angle: run the 30-report harness under 5-10 meaning-preserving prompt rewrites across two or three models and report the spread; either the sensitivity shows up in structured output or the argument needs a different leg.